Understanding Ethical AI: A Framework for Developers
Shipping Fairness: A Practical Blueprint for Ethical and Transparent AI
Introduction
Two weeks before launch, a fraud detection team calls an emergency review. Their classifier nails the ROC curve in staging but flags significantly more transactions from a particular ZIP code. Legal is worried, risk is twitchy, and engineering is staring at dashboards that don’t even log protected attributes. The model is accurate, but is it fair? And if we can’t prove it, can we ship?
Most teams hit this wall because they focus on pure predictive performance and retrofit “responsibility” as a patch. In production, that’s backwards. Fairness and transparency need to be part of the system design: how data enters, how models are trained and validated, how decisions are explained, and how runtime drift is monitored. This article lays out an engineering-first blueprint you can implement without turning your roadmap upside down.
Breaking Down the Core Concept
Ethical AI in practice means building systems that:
- Treat individuals and groups fairly according to explicitly defined criteria.
- Make decisions that can be explained, audited, and corrected.
- Respect privacy, consent, and data minimization.
- Are governed through clear documentation, approvals, and runtime monitoring.
Frameworks for fairness and transparency give developers a repeatable way to do this. They are not just policy PDFs. They are concrete patterns, metrics, documentation artifacts, and CI/CD gates that ensure ethical requirements travel with your data and models from laptop to production.
Intuition:
- Fairness addresses harmful disparities across groups (e.g., by gender, age, ZIP code). Transparency makes the “why” legible so you can debug, justify, and improve.
- If you can’t measure disparities and you can’t explain decisions, you can’t responsibly deploy.
Mechanic (what this looks like in your stack):
- Collect the right metadata (including sensitive attributes where legally permitted).
- Evaluate group-level metrics in validation, not just overall accuracy.
- Document what the model is allowed to do, how it was trained, and who approved it.
- Enforce deployment gates that fail builds if fairness thresholds aren’t met.
- Monitor fairness at runtime and feed issues back to retraining.
How It Works: Step-by-Step
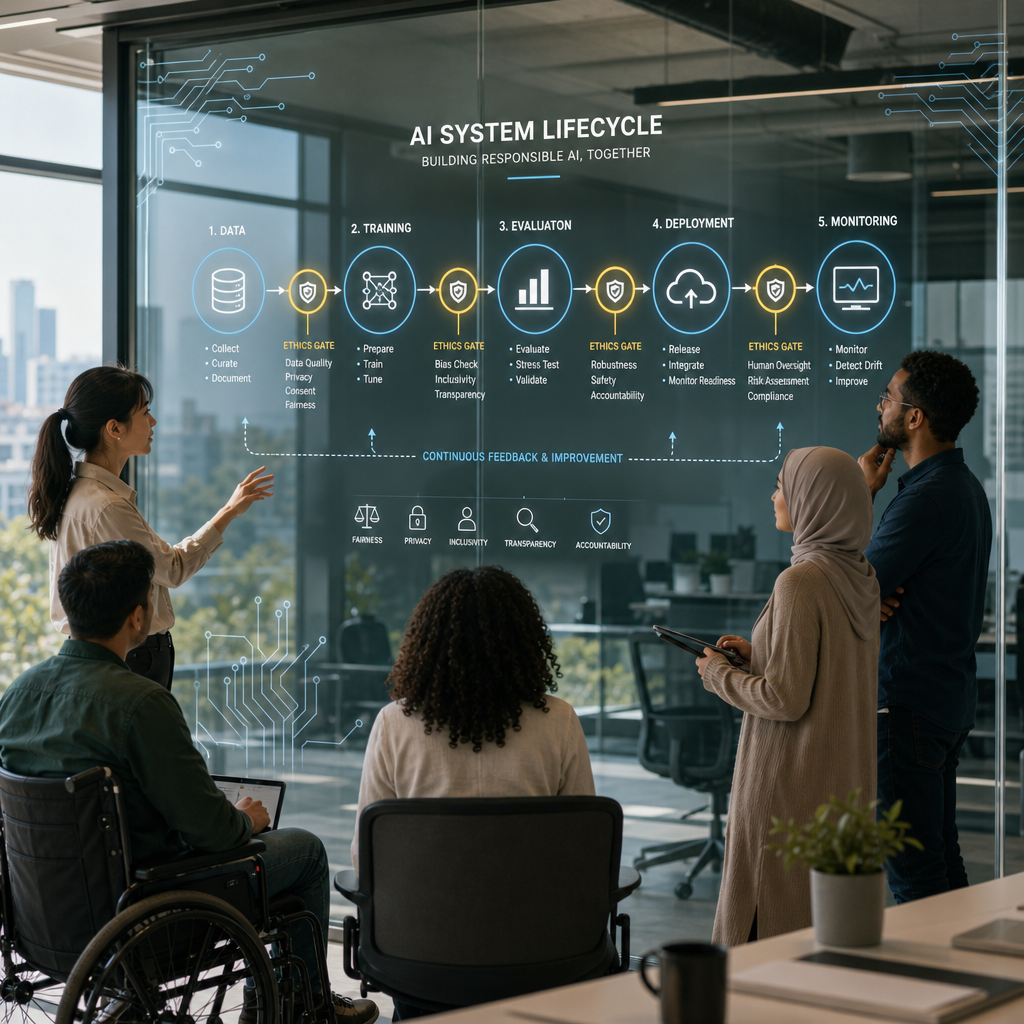
Below is an end-to-end flow that bakes ethical checks into your MLOps pipeline.
flowchart LR
                          A[Raw Data Sources] --> B[Data Profiling & Bias Scans]
                          B --> C[Feature Store with Lineage]
                          C --> D[Model Training & Hyperparameter Tuning]
                          D --> E[Validation: Accuracy + Fairness + Robustness]
                          E -->|passes thresholds| F[Transparency Artifacts: Model Card & Datasheets]
                          F --> G[Governance Review & Sign-off]
                          G -->|approved| H[Model Registry]
                          H --> I[Deployment: Batch/Online]
                          I --> J[Runtime Monitoring: Drift + Fairness + Explainability]
                          J --> K{Alerts: threshold breached?}
                          K -- yes --> L[Human-in-the-loop Triage & Incident Process]
                          L --> B
                          K -- no --> I
                          E -->|fails thresholds| L
Step-by-step:
- Data profiling and bias scans: Detect imbalanced representation, target leakage, and proxy variables. Record lineage and data consent status.
- Feature store: Version features with metadata. Tag sensitive attributes, document transformations, and enforce access controls.
- Training: Treat fairness as a first-class metric alongside accuracy. Evaluate multiple thresholds. Consider mitigations (reweighting, constraints, post-processing).
- Validation: Compute group metrics such as demographic parity difference and equalized odds difference. Generate explanations and subgroup performance dashboards.
- Transparency artifacts: Create a Model Card and Dataset Datasheet with purpose, data provenance, metrics, limitations, and known risks.
- Governance gate: Require sign-off from designated reviewers before registry promotion.
- Deployment: Preserve the same preprocessing used at training. Make explanations available where appropriate.
- Monitoring: Track drift, performance by subgroup, and explanation stability. Page on-call if fairness thresholds breach.
- Incident response: Quarantine models, roll back, notify stakeholders, and add postmortem findings to the Model Card.
The Whiteboard Analogy
Think of your AI service like a loan committee:
- Data profiling is the intake clerk checking that the application is complete and comparable.
- Fairness validation is the compliance officer verifying that applicants are judged by the same standard.
- The Model Card is the committee memo documenting why the policy exists, the numbers behind it, and its limits.
- Monitoring is the branch manager checking monthly reports to ensure the policy still works and isn’t drifting.
If any step is missing, you may approve loans quickly, but you can’t prove you did it fairly—or fix it when something goes wrong.
Architectural Trade-offs & Comparisons
|
Option or Framework |
What it primarily provides |
When to use it |
Developer impact |
Notable limitations |
|---|---|---|---|---|
|
NIST AI Risk Management Framework (RMF) |
It gives a risk-first framing with functions (Map, Measure, Manage, Govern) that teams can map to controls and metrics. |
Use it to structure a program across product, legal, and engineering without prescribing tools. |
It helps align requirements to pipeline steps and justifies gates in CI/CD. |
It is high-level and requires translation into concrete metrics and tooling. |
|
EU AI Act (risk tiers) |
It classifies systems by risk level and mandates documentation, testing, and post-market monitoring. |
Use it if you serve EU users or build high-risk categories like hiring or credit scoring. |
It forces explicit documentation, data governance, and auditing hooks in your stack. |
It is regulatory text, so engineering specifics must be implemented by you. |
|
ISO/IEC 42001 (AI Management System) |
It provides a management system standard for governing AI processes end to end. |
Use it if you need certifiable process maturity for enterprise customers. |
It drives repeatable SOPs and traceable artifacts across teams. |
It does not replace technical metrics or code-level controls. |
|
Model Cards + Datasheets for Datasets |
They standardize transparency about model purpose, data provenance, metrics, and known risks. |
Use them for every model that affects users or compliance, not just high-risk ones. |
They become living docs generated from your training/validation pipeline. |
They require discipline; without automation they go stale quickly. |
|
Fairness toolkits (Fairlearn, AIF360) |
They implement fairness metrics and mitigation algorithms you can call from Python. |
Use them in validation to quantify group disparities and test mitigation strategies. |
They add a few lines of code to your sklearn workflow and produce gated metrics. |
They need careful metric selection; optimizing one can hurt another. |
|
Interpretability tools (SHAP, LIME) |
They provide local and global explanations for model predictions. |
Use them to debug features, create user-facing rationale, and monitor explanation drift. |
They integrate into notebooks and services to expose top features per decision. |
They can be computationally expensive and sometimes unstable across runs. |
|
Governance in MLOps (MLflow + policies) |
It couples model registry with approval workflows and checks before deployment. |
Use it to block promotion when fairness or documentation is missing. |
It makes risk controls programmatic and visible to on-call. |
It requires process buy-in and reliable metadata capture. |
[!TIP] Start with Model Cards, Fairlearn metrics, and a simple governance gate in CI that fails on fairness breaches. You can add interpretability and ISO-aligned processes as you mature.
Why This Matters to Your Stack
- Better debugging: When subgroup AUC craters, explanations reveal which features behave differently, leading you directly to broken pipelines or data shift.
- Safer rollouts: Deployment gates on fairness metrics prevent accidental harm even when accuracy rises.
- Faster audits: Model Cards and data lineage remove scramble time when legal or customer security asks, “How was this trained?”.
- Scalable ops: The same monitoring you use for latency and errors can page you on fairness drift, making ethics an SLO you can run on-call.
Production Implementation & Use Cases
Where this shows up in real products:
- Credit and underwriting: Fairness gates on approval rates and error rates by protected groups with human-in-the-loop triage for borderline scores.
- Hiring and promotions: Structured documentation of datasets, explicit exclusion of proxy features, and explanation tooling for candidate decisions.
- Healthcare triage: Calibrated thresholds per subgroup with continuous monitoring for outcome disparities and clinician review for overrides.
- Content moderation: Transparent guidelines, appeal mechanisms, and per-language subgroup metrics to avoid majority-language bias.
- Fraud and abuse: Balanced precision/recall by region or merchant category with runtime explanation to justify holds.
Implementation realities:
- You need legal input to track sensitive attributes lawfully. When you can’t store them, evaluate on synthetic or held-out governance datasets offline.
- Fairness thresholds must be decided with domain experts; there is no one-size-fits-all number.
- Documentation should be generated by code in the training pipeline, not hand-written after the fact.
- Monitoring needs baselines per subgroup with confidence intervals; alert on both absolute thresholds and sudden deltas.
Provide a clean, practical, production-realistic code snippet in (Python). Use commonly available SDKs, Do not create a lengthy code. Only keep the core code logic with a comment to install PIP package e.g. use OpenAI package and ChatClient class, do not create custom LLMCient
# pip install scikit-learn fairlearn

                      from dataclasses import asdict, dataclass
                      from typing import Dict, Any
                      import json
                      import numpy as np
                      from sklearn.datasets import make_classification
                      from sklearn.linear_model import LogisticRegression
                      from sklearn.model_selection import train_test_split
                      from sklearn.metrics import roc_auc_score, accuracy_score
                      from fairlearn.metrics import (
                          MetricFrame,
                          selection_rate,
                          true_positive_rate,
                          false_positive_rate,
                          demographic_parity_difference,
                          equalized_odds_difference,
                      )

                      # 1) Create a simple binary classification problem with a simulated sensitive attribute.
                      X, y = make_classification(
                          n_samples=3000,
                          n_features=6,
                          n_informative=4,
                          class_sep=1.0,
                          random_state=42,
                      )

                      # Simulate a binary sensitive attribute correlated with feature 0
                      sensitive = (X[:, 0] > np.median(X[:, 0])).astype(int)  # 0 or 1

                      # Introduce mild base-rate disparity: flip a small portion of labels for group 1
                      flip_mask = (sensitive == 1) & (np.random.RandomState(1).rand(len(y)) < 0.10)
                      y_biased = y.copy()
                      y_biased[flip_mask] = 1  # make positives slightly more common in group 1

                      X_train, X_test, y_train, y_test, s_train, s_test = train_test_split(
                          X, y_biased, sensitive, test_size=0.3, random_state=0, stratify=y_biased
                      )

                      # 2) Train a standard model (stand-in for your production estimator).
                      clf = LogisticRegression(max_iter=200, n_jobs=1)
                      clf.fit(X_train, y_train)

                      # 3) Score and pick a working threshold.
                      proba = clf.predict_proba(X_test)[:, 1]
                      y_pred = (proba >= 0.5).astype(int)

                      overall_auc = roc_auc_score(y_test, proba)
                      overall_acc = accuracy_score(y_test, y_pred)

                      # 4) Compute fairness metrics by group using Fairlearn.
                      group_metrics = MetricFrame(
                          metrics={
                              "selection_rate": selection_rate,
                              "tpr": true_positive_rate,
                              "fpr": false_positive_rate,
                          },
                          y_true=y_test,
                          y_pred=y_pred,
                          sensitive_features=s_test,
                      )

                      dp_diff = demographic_parity_difference(y_true=y_test, y_pred=y_pred, sensitive_features=s_test)
                      eo_diff = equalized_odds_difference(y_true=y_test, y_pred=y_pred, sensitive_features=s_test)

                      # 5) Simple deployment gate: fail if disparities exceed thresholds.
                      FAIRNESS_THRESHOLDS = {"dp_abs_diff": 0.10, "eo_abs_diff": 0.10}
                      gate_pass = (abs(dp_diff) <= FAIRNESS_THRESHOLDS["dp_abs_diff"]) and (abs(eo_diff) <= FAIRNESS_THRESHOLDS["eo_abs_diff"])

                      # 6) Build a lightweight Model Card payload you can save or attach to your registry entry.
                      @dataclass
                      class ModelCard:
                          model_name: str
                          purpose: str
                          data_overview: Dict[str, Any]
                          training_metrics: Dict[str, float]
                          fairness_metrics: Dict[str, Any]
                          decision_thresholds: Dict[str, Any]
                          limitations: str
                          approvals: Dict[str, Any]

                      model_card = ModelCard(
                          model_name="fraud_score_v3",
                          purpose="Classify transactions with likely fraud for manual review.",
                          data_overview={
                              "n_features": X.shape[1],
                              "sensitive_attribute": "simulated_binary_group",
                              "notes": "Sensitive attribute retained only for offline fairness evaluation.",
                          },
                          training_metrics={
                              "auc": round(overall_auc, 4),
                              "accuracy": round(overall_acc, 4),
                          },
                          fairness_metrics={
                              "groups": {
                                  "0": {k: float(v) for k, v in group_metrics.by_group[0].items()},
                                  "1": {k: float(v) for k, v in group_metrics.by_group[1].items()},
                              },
                              "demographic_parity_difference": float(dp_diff),
                              "equalized_odds_difference": float(eo_diff),
                              "thresholds": FAIRNESS_THRESHOLDS,
                              "deployment_gate_passed": gate_pass,
                          },
                          decision_thresholds={"score_cutoff": 0.5, "rationale": "Selected for balanced precision/recall in pilot."},
                          limitations=(
                              "Does not include real-world distribution shifts, merchant-specific behaviors, or temporal effects. "
                              "Fairness metrics are evaluated on held-out data; runtime drift may alter parity."
                          ),
                          approvals={"risk_review": "pending" if not gate_pass else "approved_conditionally"},
                      )

                      # 7) Persist artifacts for audit and registry linking.
                      with open("model_card_fraud_score_v3.json", "w") as f:
                          json.dump(asdict(model_card), f, indent=2)

                      print(f"AUC={overall_auc:.3f} ACC={overall_acc:.3f}")
                      print("By-group metrics:", group_metrics.by_group)
                      print("DP diff:", round(dp_diff, 4), "EO diff:", round(eo_diff, 4))
                      print("Deployment gate passed:", gate_pass)
                      print("Wrote model_card_fraud_score_v3.json")
What this snippet demonstrates:
- You measure fairness with the same rigor as accuracy using Fairlearn’s MetricFrame.
- You enforce a programmatic deployment gate on fairness thresholds.
- You generate a machine-readable Model Card that can be attached to your model registry entry.
- You isolate sensitive attributes for offline evaluation, avoiding their use at inference where inappropriate.
[!WARNING] Metric choice is contextual. Demographic parity, equalized odds, and equal opportunity can conflict. Pick one or two that match your domain harm model and document the trade-off in the Model Card.
demonstrating a real application pattern of this concept.
Pattern you can adopt this sprint:
- Training pipeline step: Compute accuracy and at least two fairness metrics by subgroup. Emit JSON artifacts with raw and aggregated metrics.
- CI/CD gate: Parse the artifacts and fail promotion if thresholds are breached or if the Model Card is missing required fields.
- Registry policy: Require a Model Card, Datasheet, and approval record before marking a model as “staging” or “production.”
- Runtime monitors: Recompute subgroup selection rates daily or weekly using a sample of predictions with delayed ground truth. Alert if drift or disparity exceeds baselines.
- On-call runbook: Define rollback, incident classification, stakeholder notification, and a process to update the Model Card post-incident.
Keep it focused, clean, and thoroughly commented.
Practical guardrails for teams:
- Define harm and stakeholders early: You cannot optimize what you have not named. Write down which harms matter (e.g., false negatives in healthcare triage) and which groups you must protect.
- Calibrate thresholds with domain experts: A strict demographic parity target might be inappropriate in fraud detection where base rates differ by merchant category; equalized odds might be a better fit.
- Beware proxy features: ZIP code, device type, or time-of-day can act as proxies. Use correlation analyses and explanation tools to detect indirect discrimination.
- Automate documentation: Generate Model Cards and Datasheets from code so they update on each training run.
- Privacy by design: Collect only what you need, enforce retention windows, and restrict sensitive-attribute access to offline evaluation contexts with audit logs.
- Close the loop: Tie monitoring alerts to retraining and governance updates. Ethics without ops is a memo; ethics with ops is a system.
[!TIP] Start small: Add two fairness metrics to validation, a JSON Model Card artifact, and a single CI gate. Once the workflow sticks, layer in interpretability and runtime disparity monitors.
Comments
Loading comments…